Model training on your data
Fine-tuning
SFT/LoRA of open LLMs for your domain and style.
Inference optimization
Quantization, distillation, speculative decoding. Fewer GPUs — faster answers.
RAG and agents
Search over your documents with citations and prompt-injection protection.
ML security
Pipeline audits against OWASP LLM Top 10 and MITRE ATLAS.
Own hardware
We deploy locally: from a workstation to a K8s cluster and ARM SBCs.
Transparency
Before/after benchmarks, model card, reproducible pipeline.
Blog
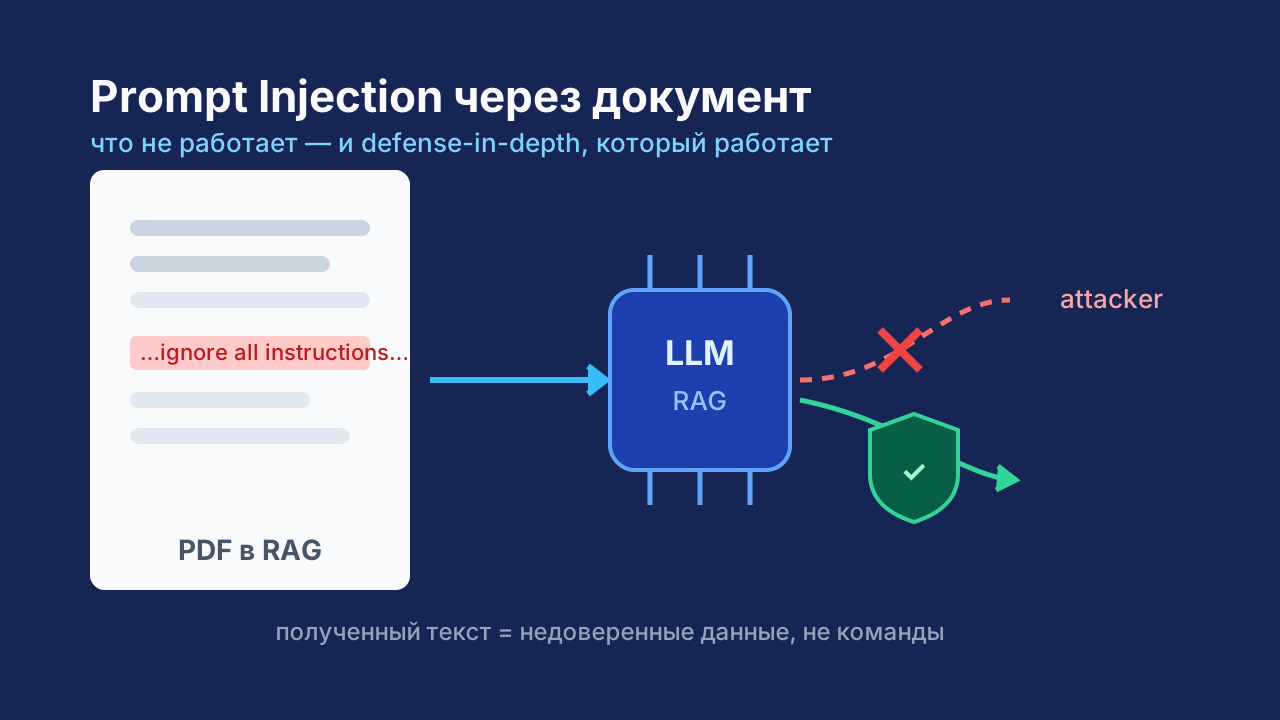
Prompt injection in RAG: attack through your own document
In corporate RAG the context source is your own documents. If an indexed PDF has an instruction embedded — “ignore previo...
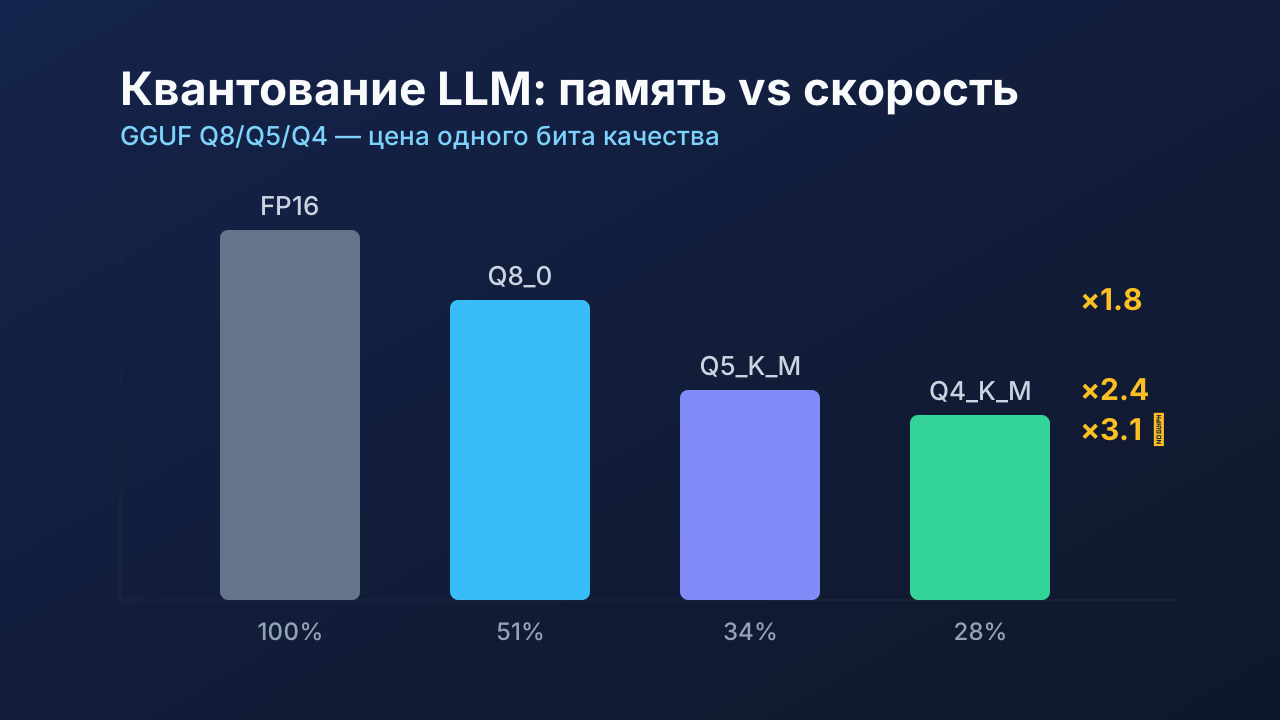
LLM quantization: how much quality does one bit cost
Quantization is the cheapest way to speed up inference, but the “free cheese” ends at Q4. We ran three open models ...