Blog
Notes on model optimization and AI security.
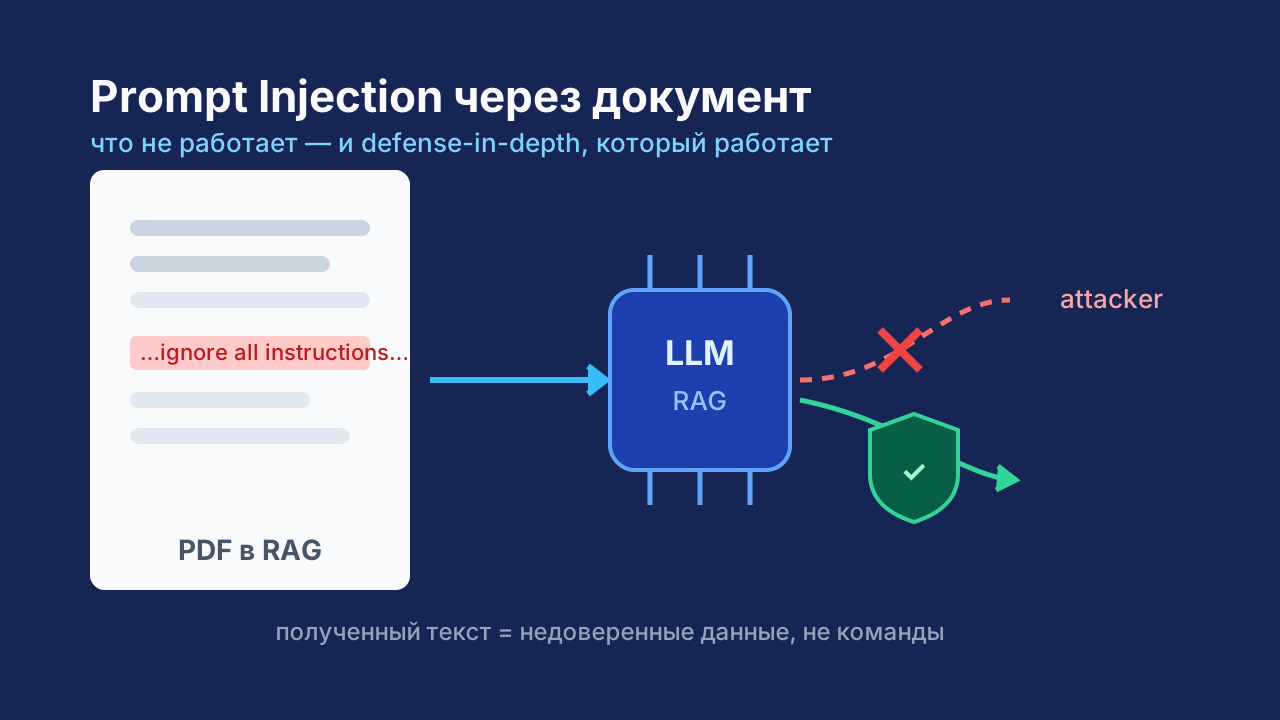
Prompt injection in RAG: attack through your own document
In corporate RAG the context source is your own documents. If an indexed PDF has an instruction embedded — “ignore previo...
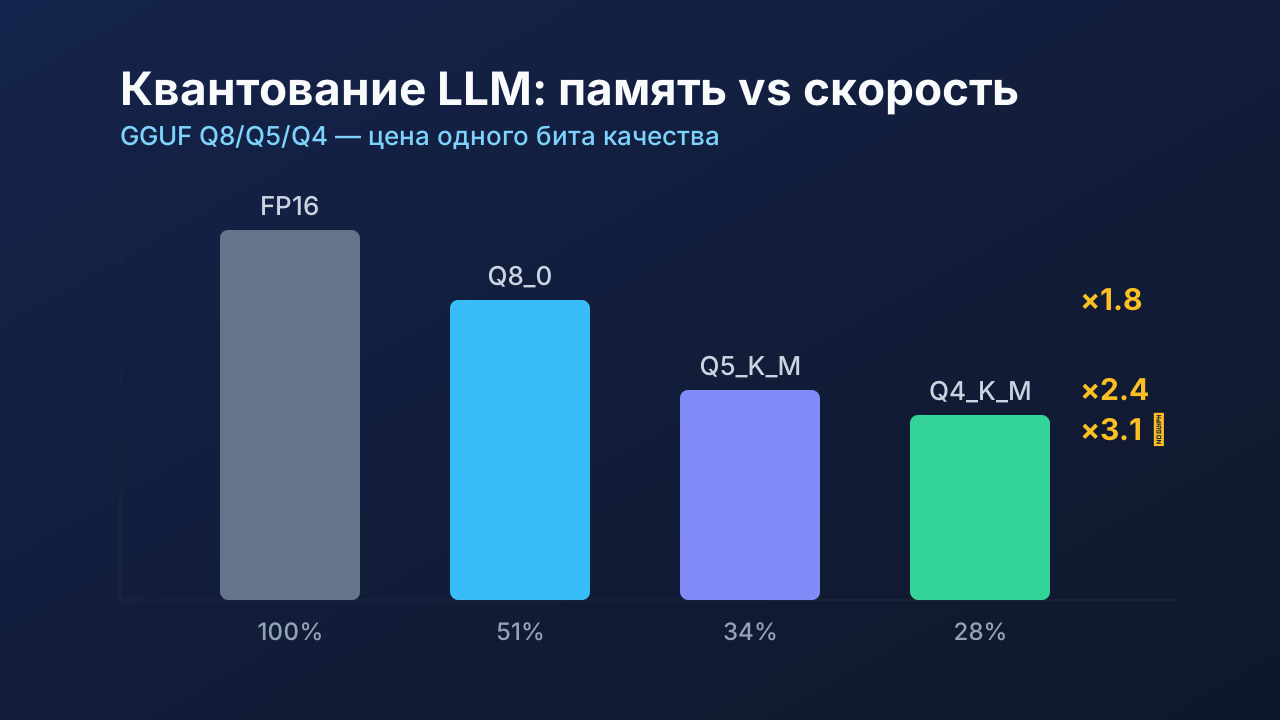
LLM quantization: how much quality does one bit cost
Quantization is the cheapest way to speed up inference, but the “free cheese” ends at Q4. We ran three open models ...